Using an AI Coding App Next to Bubble: Which Tasks to Delegate and Which to Do by Hand
A practical decision guide for non-technical founders launching an MVP: how I pair Bubble with an external AI assistant, what I delegate, what I keep visual, and how I verify the output.
When you need to validate a product idea, launch an MVP, and collect early customer feedback or investor interest, development speed is everything. If you're a non-technical founder into vibe coding, pairing no-code tools with generative assistants feels like an unfair advantage. It looks like every technical roadblock can be solved with a quick prompt. Same topic: Claude Code 2.1.287: What Non-Technical.
That's where it goes wrong. Bubble is not a traditional text-based repository. It's a visual runtime environment with its own relational database, client-server lifecycle, and strict security model. Try to automate the whole build with an ai coding app and you often end up with subtle vulnerabilities, broken workflows, and data leaks before your first real user signs up. To move fast without undermining the launch, I divide the work using a clear framework. Same topic: IT Brew: business vibe-coding without. Same topic: Bubble MCP: A First-Connection Checklist. Worth reading next: Why You Don't Need ai.
1. Tasks to Delegate: Drafts, Payloads, and Plain-Text Logic
External AI coding tools are good at self-contained text, code skeletons, and structural templates. A human builder inspects the output before pasting it into Bubble.
- Plugin JavaScript skeletons (Plugin Editor): When the MVP needs capabilities beyond standard elements, custom JavaScript belongs in Bubble's Plugin Editor. First drafts of element actions (
initialize,update,run_action) or client/server actions (run_client,run_server) are safe to delegate. You get a functional baseline without architecting complex JavaScript from scratch. - Sample API payloads and curl commands: When I integrate a third-party platform through the API Connector, I hand the API documentation to an AI tool and get clean JSON request bodies and curl examples back. Then I configure them manually.
- Logic explanation and pseudocode review: Describe complex operational rules in plain English, and the model can spot logical bottlenecks, circular loops, or unhandled states before you build the actual workflows.
- Test data and edge-case generation: AI assistants quickly produce edge-case arrays (unusual character encodings, boundary numeric values, empty strings) for testing custom workflow conditions.
- Documentation and comments: Maintenance notes or README documentation for your proprietary private plugins. A closer look: Community AI Toolkit for Bubble:.
2. Tasks to Keep in the Bubble Visual Editor
Anything that directly configures Bubble's internal engine, database schema, or live integrations, I do by hand in the editor.
- Visual workflows (Page and Backend Workflows): Step-by-step logic, UI events, element visibility, and page transitions belong in Bubble's visual editor. They depend on the visual state of the app, and raw generated text can't reliably reproduce that.
- Database architecture and fields: Data Types, custom fields, and relational links need an understanding of how Bubble searches and caches data. Copy traditional SQL structures and you often get poor page performance.
- API Connector setup and initialization: Clicking "Initialize call" in the API Connector sends a live request to the destination endpoint. Bubble uses that response to build the permanent schema your whole app relies on. I do this step manually so live endpoints don't get modified by accident and production data doesn't get baked into the app's source definition.
- Dynamic expressions and UI properties: Binding visual components, building dynamic search expressions (
Do a search for), and applying responsive layout settings have to happen natively in the Property Editor.
3. High-Risk Areas Requiring Explicit Human Review
These surfaces carry critical security and operational consequences. I never deploy changes here without a manual review.
- Privacy Rules (Data tab): Privacy rules are server-side access controls, and Bubble names them the primary defense for user data. Hand access control to autonomous ai coding agents without close oversight and you invite critical data exposure. For apps that handle sensitive user information, Bubble recommends enabling Strict search privacy mode.
- Backend API Workflows and "Ignore privacy rules": Unlike standard page workflows, backend API workflows can override privacy rules entirely. An unauthenticated public endpoint, or broadly skipped privacy checks, can let unauthorized visitors extract or alter entire database tables.
- Third-party npm dependencies: When AI models draft server-side plugin actions, they sometimes hallucinate package names that don't exist. One unverified package reference can introduce security risks or break backend execution.
- Custom scripts in HTML elements or Toolbox: Scripts inside visual HTML elements run only in run mode, not in the editor. Community bridges like the Toolbox plugin (
Run javascript,Javascript to Bubble) are third-party tools, not native core features. Any user input that passes through them needs careful sanitization. - Platform hard limits: Server-side plugin scripts and external API calls run under strict execution timeouts and a hard 50 MB response payload limit. AI models rarely account for these boundaries on their own. Same topic: Community AI Toolkit for Bubble:.
Pre-Implementation Review Checklist
Before any AI-suggested code or API payload goes into my Bubble project, I run through this list:
- Surface verification: Does this snippet belong in the Plugin Editor, or was it generated by mistake for an interface that needs a native visual workflow?
- Plugin API v4 standards: If it's plugin code, does it follow the modern async/await and promise handling that Bubble's Plugin API v4 requires?
- Safe API initialization: Did you use safe, mocked test parameters during API Connector initialization, so sensitive credentials and production records stay out of the schema?
- Principle of least privilege: Did you manually review the privacy rules on the Data tab and confirm sensitive fields are hidden from unauthenticated or unauthorized users?
- Dependency and quota verification: Do all suggested npm packages actually exist in official registries? Does the logic respect Bubble's execution timeouts and 50 MB limits?
- Isolated testing: Did you test the entire workflow in the Development branch before deploying it to the Live environment for real customers?
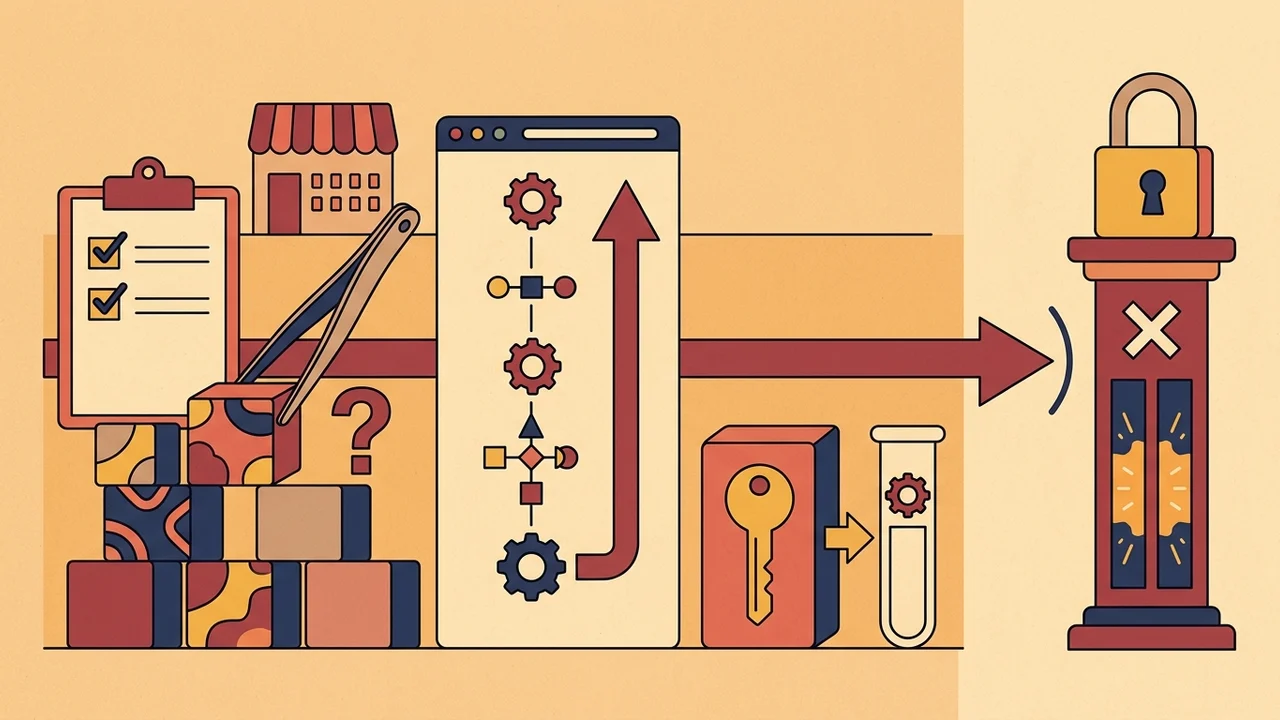
| Check | What to verify | What to avoid |
|---|---|---|
| Surface verification | Confirm the snippet belongs in the Plugin Editor | Using plugin code where a native visual workflow is required (or vice versa) |
| Plugin API v4 standards | Plugin code follows modern async/await and promise handling required by Bubble's Plugin API v4 | Plugin patterns that do not meet v4 async/promise requirements |
| Safe API initialization | Use safe, mocked test parameters during API Connector initialization | Exposing sensitive credentials or production records in the schema |
| Principle of least privilege | Manually review Data tab privacy rules; confirm sensitive fields are hidden from unauthenticated or unauthorized users | Leaving sensitive fields visible to unauthenticated or unauthorized users |
| Dependency and quota verification | Confirm suggested npm packages exist in official registries; confirm logic respects Bubble's execution timeouts and 50 MB limits | Non-existent packages or logic that exceeds timeouts or the 50 MB limit |
| Isolated testing | Test the entire workflow in the Development branch before deploying to Live | Deploying untested workflows to Live for real customers |